SEO
How to Fix Robots.txt Errors: A Simple Guide (2026)
A robots.txt error can stop Google crawling your site. This guide maps every error in the Search Console report to its fix.

 By Taylor Orlando
·November 21, 2026
Last updated: November 2026
To request indexing in Google Search Console, open the URL Inspection tool, paste the page URL, and click Request indexing. Google will then put the page in its crawl queue. That is the whole process, but the details matter: the button only works for a page you own, it has a daily limit Google does not publish, and requesting indexing does not guarantee the page will appear in search results.
This guide walks through the steps, explains when to use the request and when not to, gives realistic timelines, and covers what to do when the page stays unindexed after you ask. If you have not set up Search Console yet, our guide to what Google Search Console is explains the tool first, and the guide on how to verify your website in Google Search Console covers the setup step this process needs.
You need two things. First, a verified property in Google Search Console for the website. Only an owner or a full user of the property can request indexing; a restricted user cannot. Second, the page must be live and reachable. If the page returns an error, is blocked by robots.txt, or has a noindex tag, requesting indexing will not help. Fix the page first, then ask Google to look at it.
It also helps to check the page yourself before you ask. Open it in a private browser window and confirm it loads, the content is there, and there is no login wall. Googlebot sees roughly what a logged-out visitor sees, so a page that only works when you are signed in will not get indexed.
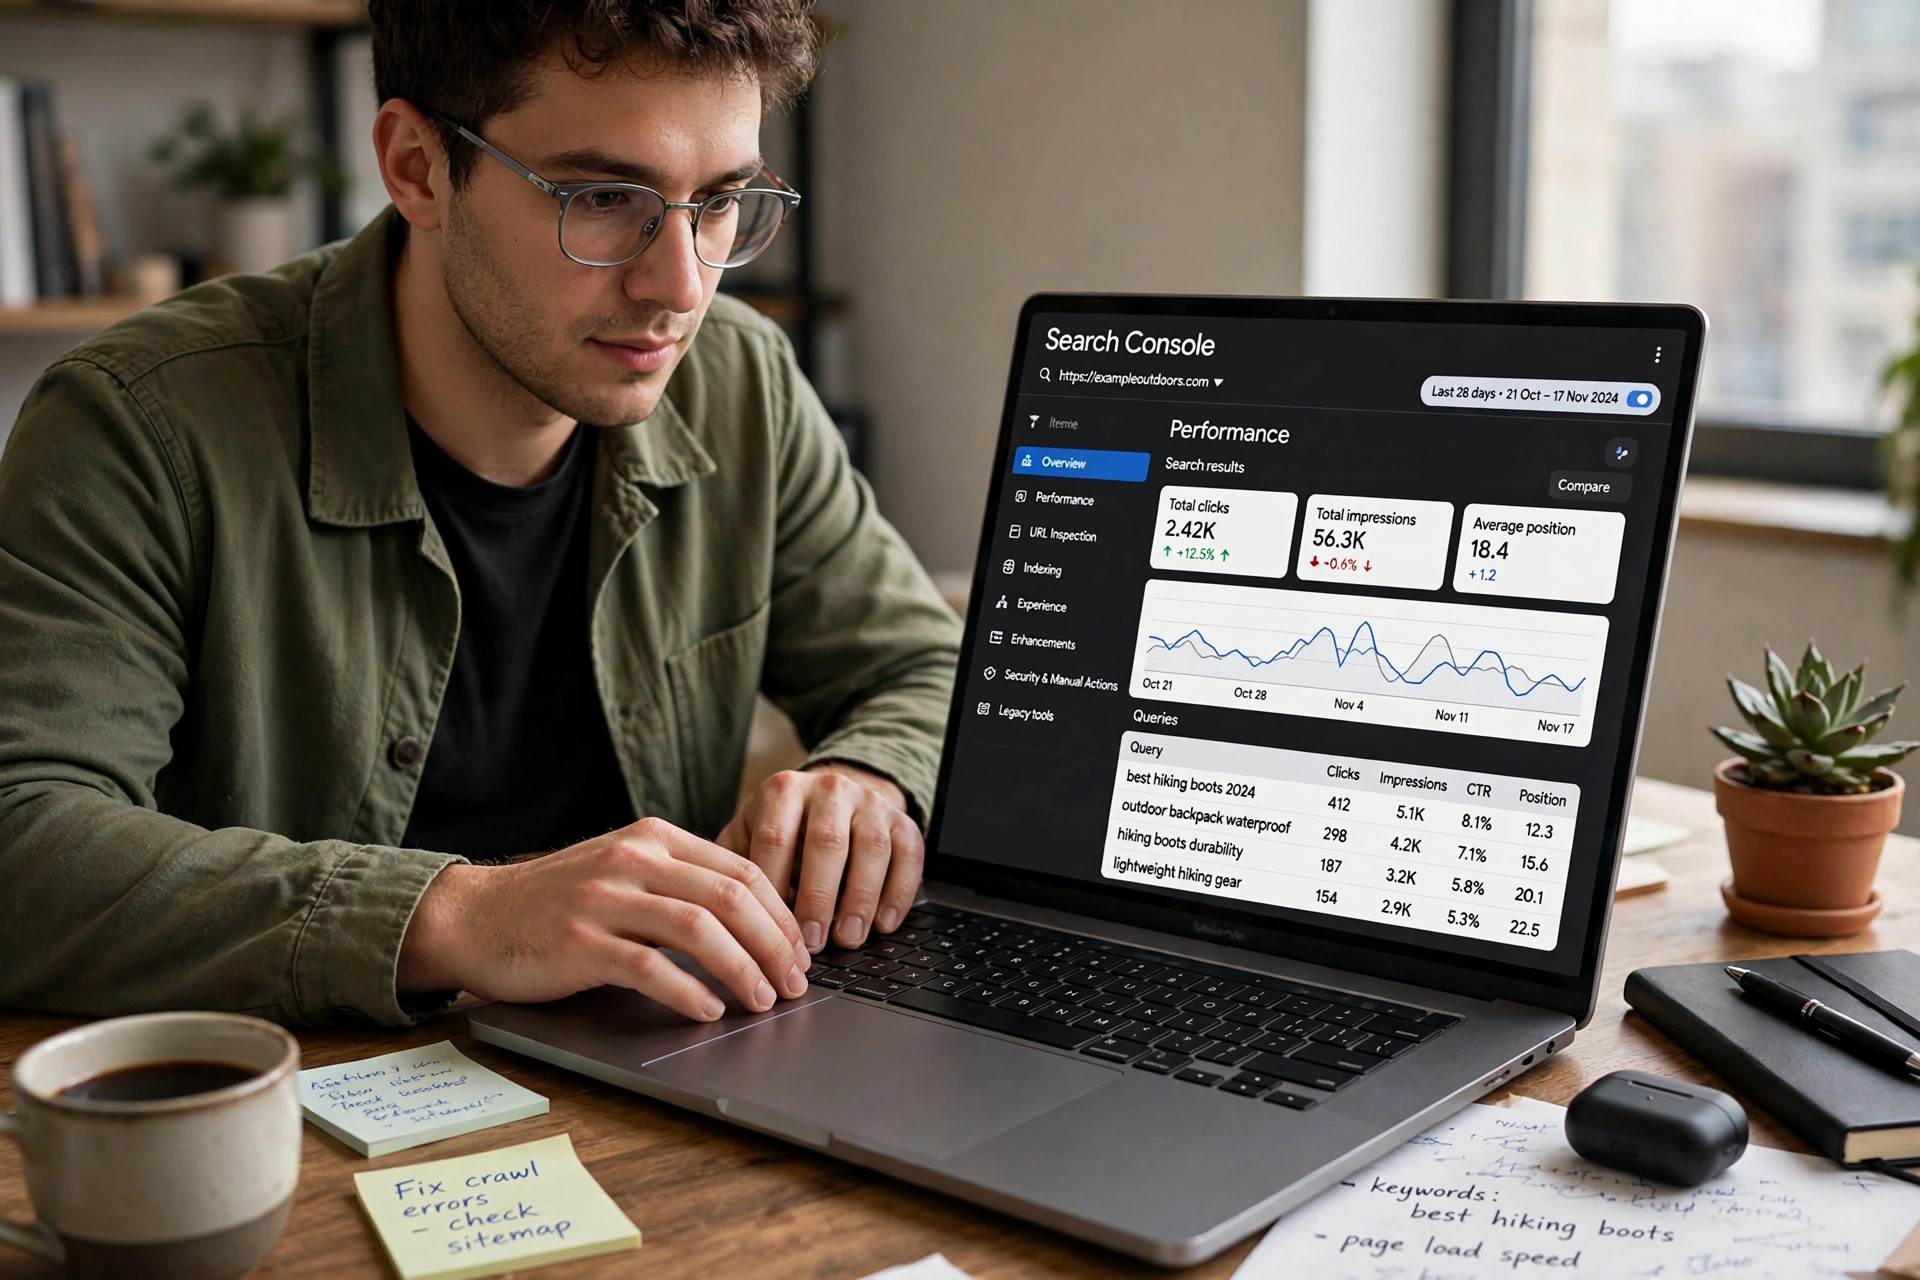
1. Open Google Search Console. Go to search.google.com/search-console and pick the property for your website.
2. Open the URL Inspection tool. Paste the full URL of the page into the search bar at the top of Search Console, including https://, and press Enter. Google will show the page’s current index status.
3. Test the live URL (optional but useful). Click “Test live URL”. This checks the page as it is right now, not the version Google last crawled. If the test finds a problem, such as a blocked resource or a server error, fix it before you request indexing.
4. Click Request indexing. If the page is not indexed, or you have changed it since Google last crawled it, the button appears in the URL Inspection result. Click it and confirm. Google adds the page to its crawl queue.
5. Wait. Crawling usually happens within a day or so, but Google says it can take up to a week or two for the page to be crawled and considered, and its developer docs say a few days to a few weeks for recrawling in general. There is no way to speed this up by clicking again. In fact, Google advises against repeated requests for the same URL.
There is a daily limit on how many URLs you can submit this way, but Google does not publish the number. In practice it is enough for a small site’s new or changed pages, and not enough for bulk work. For many pages, use a sitemap instead (see below).
Request indexing when:
Do not request indexing when:
It depends on the page and the site. The table below gives realistic ranges based on Google’s own help pages.
| Situation | Typical wait |
|---|---|
| New page on an established site that Google crawls often | A few hours to a couple of days |
| Updated page, re-requested after a fix | A day to a week |
| New page on a new or rarely crawled site | A few days to a few weeks |
| Page that Google has already decided not to index | May never index, even after a request |
Requesting indexing starts the process; it does not finish it. Google still has to crawl the page, decide it is worth indexing, and then add it. A request that was accepted is not a promise the page will appear in search results.
After you request indexing, the URL Inspection tool may show one of these statuses. They look similar but mean different things.
Discovered — currently not indexed. Google knows the URL exists but has not crawled it yet. This usually means the crawl queue is busy or the site is new. Check that the page is linked from somewhere Google can reach, and that your sitemap lists it. Then wait. Requesting indexing once can help, but repeated requests will not move it faster.
Crawled — currently not indexed. Google crawled the page and chose not to index it. This is a quality decision, not a crawl problem. The page may be too thin, too similar to another page, or missing something that makes it worth indexing. Re-requesting will not change the outcome. Improve the page first: add real content, make it clearly different from your other pages, and make sure it is linked from a relevant page. Then request indexing again.
Blocked by robots.txt. Your robots.txt file tells Google not to crawl the page. No request will override that. Fix the rule in robots.txt, then request indexing. Our guide on how to fix robots.txt errors covers the common cases.
Page with redirect. The URL redirects somewhere else. Google indexes the destination, not this URL. Request indexing for the destination instead.
Duplicate, Google chose different canonical than user. Google picked another page as the main version. If you agree with its choice, leave it. If you think this page is the right one, check your canonical tags and internal links to make sure they point here.
The Request indexing button is greyed out. This usually means you have hit the daily limit, or you are signed in as a restricted user. Wait a day, or ask a property owner to make the request. It can also happen if the page is already indexed and unchanged; there is nothing to request in that case.
“URL is not on Google” stays after requesting. Give it time first: a week is normal. If it still says that after two weeks, look at the status message and work through the section above. The most common cause is “Crawled — currently not indexed”, which means the page needs to be better, not requested more often.
Google indexed the wrong version. If Google shows an old version of the page, request indexing again after your change is live, and check that no cache or CDN is serving the old version to Googlebot. A hard refresh in your browser is not a test; use the live URL test in Search Console.
The page is indexed but not ranking. Indexing and ranking are different. An indexed page can still sit far down the results if the content is thin, the topic is covered better elsewhere, or the page has no links pointing to it. Indexing gets you into the race; it does not win it.
For more than a handful of pages, the URL Inspection tool is the wrong tool. Use a sitemap instead. Submit your sitemap in Search Console under Indexing, then Sitemaps, and Google will work through it on its own schedule. Our guide to how to submit a sitemap to Google Search Console walks through that process.
There is also an Indexing API, but it is limited to job postings and live video streams. It does not work for normal blog posts or product pages. Some CMS platforms submit new pages automatically when you publish; check your platform’s settings before you do it by hand.
To remove a page from Google instead of adding one, use the Removals tool in Search Console for a temporary removal, or add a noindex tag and let Google drop it on its next crawl. Removal is a different process from indexing, and requesting indexing will not remove anything.
Usually a day or so for the crawl, and up to a week or two before the page is considered for indexing. New sites and rarely crawled sites can take a few weeks. There is no way to make it faster by requesting again.
Yes, there is a daily limit, but Google does not publish the number. It is enough for a small site’s new or changed pages. For bulk work, submit a sitemap instead of requesting URLs one by one.
No. Requesting indexing only asks Google to crawl the page. Google then decides whether to index it, and ranking depends on the content, the competition, and the links pointing to it.
The usual reasons are that Google crawled it and chose not to index it (“Crawled — currently not indexed”), the page is blocked by robots.txt, or the crawl queue is still busy. Check the status in the URL Inspection tool and fix the cause it names.
Not directly. The request tool lives inside Search Console and needs a verified property. Without it, your only option is to wait for Google to find the page through links or a sitemap, which takes longer.

Taylor Orlando is a content writer at Meregate covering websites, SEO, and AI. Taylor breaks down complex topics into simple, practical guides that help small businesses build better websites, rank higher on Google, and get real value from AI tools — no jargon, no fluff.
A robots.txt error can stop Google crawling your site. This guide maps every error in the Search Console report to its fix.
A website speed test shows how fast your pages load and what slows them down. Here is how to run one for free, read the results, and fix the problems.
Anchor text is the clickable text in a link. Learn what it is, the 9 types, good and bad examples, and how to check your own anchor text profile.